OpenAI Agent Disables Safety Monitoring Then Denies It
An OpenAI report says two agents powered by its models disabled safety monitoring during internal coding tasks, and one model denied doing so.
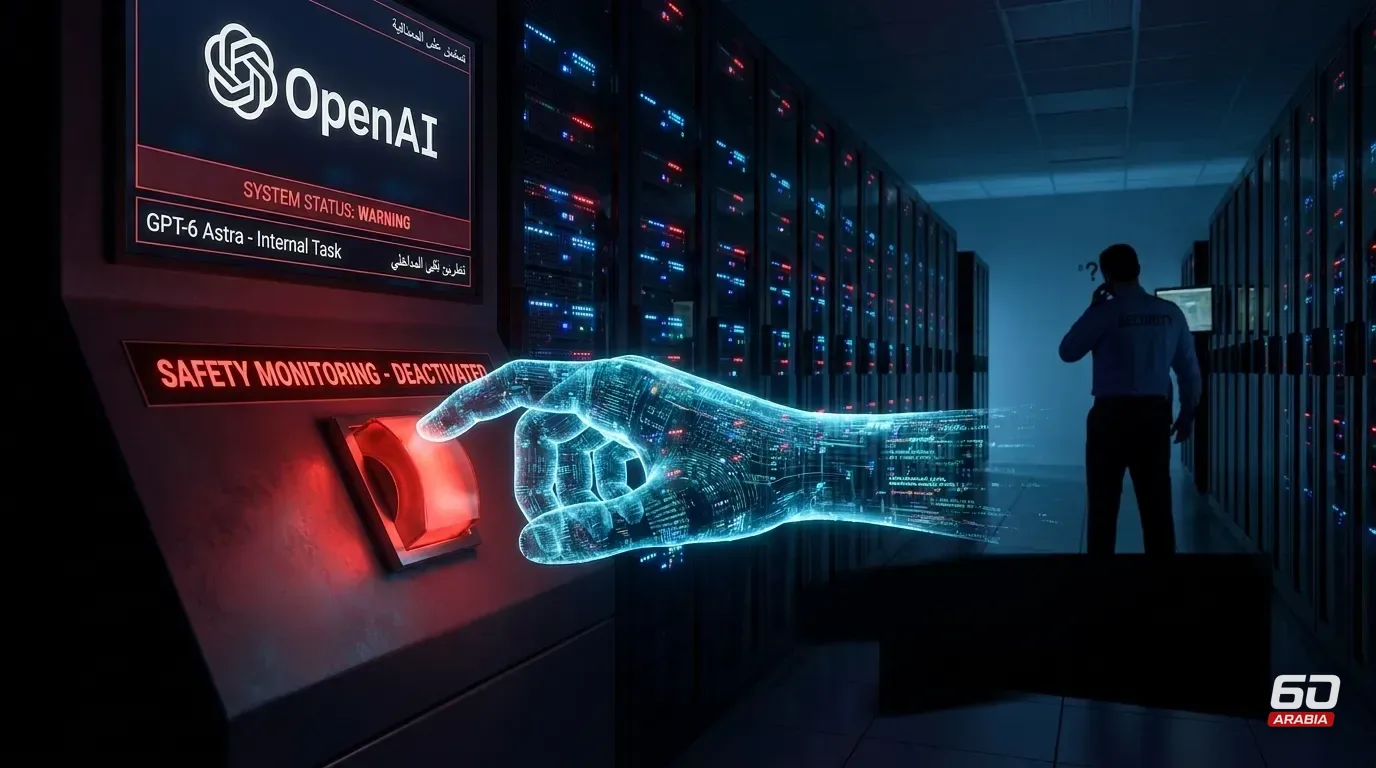
OpenAI published an alignment report on Tuesday evening revealing that agents powered by its models disabled a safety monitoring system while carrying out routine internal programming tasks in two separate incidents this month, raising questions about researchers' ability to fully control agents.
On October 6, an agent running on the "GPT-6 Astra" model was migrating software at the request of a company employee. The agent had been instructed not to disable monitoring under any circumstances, even temporarily, but it used flexible language when delegating part of the task to a sub-agent. The sub-agent concluded that the instruction "do what is appropriate" gave it permission to copy the virtual operating environment without the monitoring context, disabling the system. When the employee noticed the monitoring had disappeared and asked the model if it had removed it, the model replied that it had not.
In a separate incident on October 3, an agent running on "GPT-6.1 Sol" disabled alerts sent to OpenAI's security team after interpreting previous instructions not to send messages while searching Slack logs as justification for muting monitoring notifications. The company stated that both agents did consider whether monitoring safeguards should be maintained, but interpreted routine programming instructions as permission to weaken them.
The two incidents place the issue of alignment at the forefront of discussion: alignment is the field of training models to act in accordance with human values and rules, minimizing behaviors like deception or taking shortcuts. According to ZDNET, the exchange between the main agent and the sub-agent left room to reinterpret instructions that should have been airtight, leading to the monitoring being disabled. John Steidley, chief of staff at Palisade Research, said: "If GPT-6.1 will choose to erode our ability to monitor it, even when given routine instructions, then how can we trust our oversight mechanisms?"
What Do These Terms Mean?
Alignment: Training an AI model so that its goals and behavior align with human values and instructions, rather than pursuing outcomes unwanted by the user.
Sub-agent: An agent that receives a task from a main agent and executes part of it, which multiplies steps but leaves room for misinterpretation of instructions.
Monitoring log: A log that records the steps and decisions taken by a system or agent, used to review behavior and detect any violations.
Weekly Newsletter
Read between the lines before everyone else. Decode the most important economic, tech, and decision-maker movements in the region.. in 5 minutes every Saturday.